I build agents that answer in seconds.
Solutions architect for agents, knowledge graphs and real-time data, in Chicago.
Routes the question with the knowledge graph as context. It replaced three legacy classifiers.
Numbers from production
- 91%# valid SQL from an NL-to-SQL planner, up from 77%
- 1M+# Kafka writes a day into MongoDB
- 11.3M# champion/challenger comparisons, zero mismatches
- 100%# UAT queries answered in under 7 s by a 12-node agent
Agents, graphs, streams and the plumbing
Five things I build for a living, each with the pattern behind it.
Agents grounded in a knowledge graph
LangGraph agents over Neo4j. Retrieval runs in parallel, one composer writes, and a verifier gate checks every answer before a user sees it.
question
   |
[ intent_router ] ---- knowledge graph
   |
   +--------------+---------------+
   |              |               |
[ vector ]   [ full-text ]   [ graph ]     # in parallel
   |              |               |
   +------- rank fusion ----------+
                  |
            [ compose ]                    # one writer
                  |
          [ verifier_gate ]                # grounded, judged
                  |
               answer
The model never writes the SQL
Gemini picks entities, columns and filters from graph metadata. A deterministic planner builds the joins and safe casts, then dry-runs the query in BigQuery.
# 1. the model returns a plan, not SQL
{
  "entity":  "accounts",
  "columns": ["opened_on", "balance"],
  "filters": [{"column": "balance", "op": ">", "value": 0}]
}

# 2. the planner compiles it and dry-runs it
SELECT a.opened_on,
       SAFE_CAST(a.balance AS NUMERIC) AS balance
FROM   `example.accounts` AS a
WHERE  SAFE_CAST(a.balance AS NUMERIC) > 0
-- dry run passedEvent streams that close the loop
Kafka pipelines carry every click, dismissal and acknowledgment into MongoDB, so the personalization models learn from what members actually do.
| Offset | Event | Action |
|---|---|---|
| 48211 | action.clicked | act-2041 |
| 48212 | action.dismissed | act-0377 |
| 48213 | action.acknowledged | act-1185 |
| 48214 | action.clicked | act-0912 |
| 48215 | action.clicked | act-2041 |
| 48216 | action.dismissed | act-0560 |
| 48217 | action.acknowledged | act-0377 |
| 48218 | action.clicked | act-1730 |
Async Python that stays async
FastAPI services, SSE and MCP endpoints, and job queues on plain Postgres. Halving one chat API’s latency meant unblocking 13 call sites.
--- before
+++ after
    rows = graph.run(cypher, q=q)  # blocks the loop
    rows = await asyncio.to_thread(graph.run, cypher, q=q)

# a job queue with no extra infrastructure
SELECT id FROM jobs
WHERE  state = 'queued'
ORDER BY id
FOR UPDATE SKIP LOCKED
LIMIT 1;Guardrails live in the data layer
Access rules are enforced in retrieval, not the prompt, and CI fails if any graph query skips the gate. Everything is traced with OpenTelemetry and Langfuse.
# fails the build if any Cypher query skips the gate
def test_every_query_is_gated():
    for call in cypher_calls(ast.parse(SOURCE)):
        assert ACCESS_GATE in call.query, (
            f"{call.location} skips the access gate"
)From credit research to agents
Twelve years, newest first. Open a row for more.
2025 to nowNuscaleSolutions Architect, Data & AI
Agentic GenAI platform for a major U.S. credit bureau.
- Multi-agent services on LangGraph and Vertex AI Gemini over a Neo4j knowledge graph, with the taxonomy, ontology and pgvector embeddings as the semantic layer.
- A 12-node chat agent: median latency from 20 to 30 s down to 3.8 s, every UAT query under 7 s, search accuracy from 26% to 49%.
- A champion/challenger engine on a Postgres job queue: 11.3M comparisons, zero discrepancies, days of checking down to under a minute.
- NL-to-SQL where a deterministic planner, not the model, writes the SQL. Valid queries up from 77% to 91%.
- MCP servers over SSE, OpenTelemetry and Langfuse tracing, LLM-as-a-judge evaluation, Kubernetes via Helm.
2020 to 2025Elevance HealthData Science Solution Consultant Sr
Real-time personalization APIs and Kafka pipelines.
- Led the Next Best Actions API: Flask microservices serving real-time ML inference to the mobile app and web portal, at an 8% click-through rate.
- Fault-tolerant Kafka pipelines writing 1M+ events a day into MongoDB as a feedback loop for the models.
- Real-time and batch inference on AWS EKS with autoscaling, plus Spark Structured Streaming pipelines.
2018 to 2020AccentureData Engineering Sr. Analyst
Spark pipelines that forecast member calls and claims.
- ETL, analytical datasets and scoring pipelines for predictive models.
- Moved legacy HQL and Teradata SQL to Spark Scala and Spark SQL for throughput.
2018KogentixBig Data Developer
Hadoop ingestion and Spark SQL for retail and logistics clients.
- Automated Sqoop ingestion from Oracle, MySQL and DB2 into HDFS as Parquet, ORC and Avro.
2010 to 2015CRISIL Global Research & AnalyticsResearch Analyst
Credit models for 150+ high-yield issuers, read by 600+ institutional clients.
- US CMBS and UK RMBS/ABS tracker models from Bloomberg data, and modeling workflows automated in Excel VBA.
A copilot, a forecast, a heartbeat
Side projects, built on my own time.
WealthPanda
Reads your accounts, scores what you own and briefs you in plain English.
How it works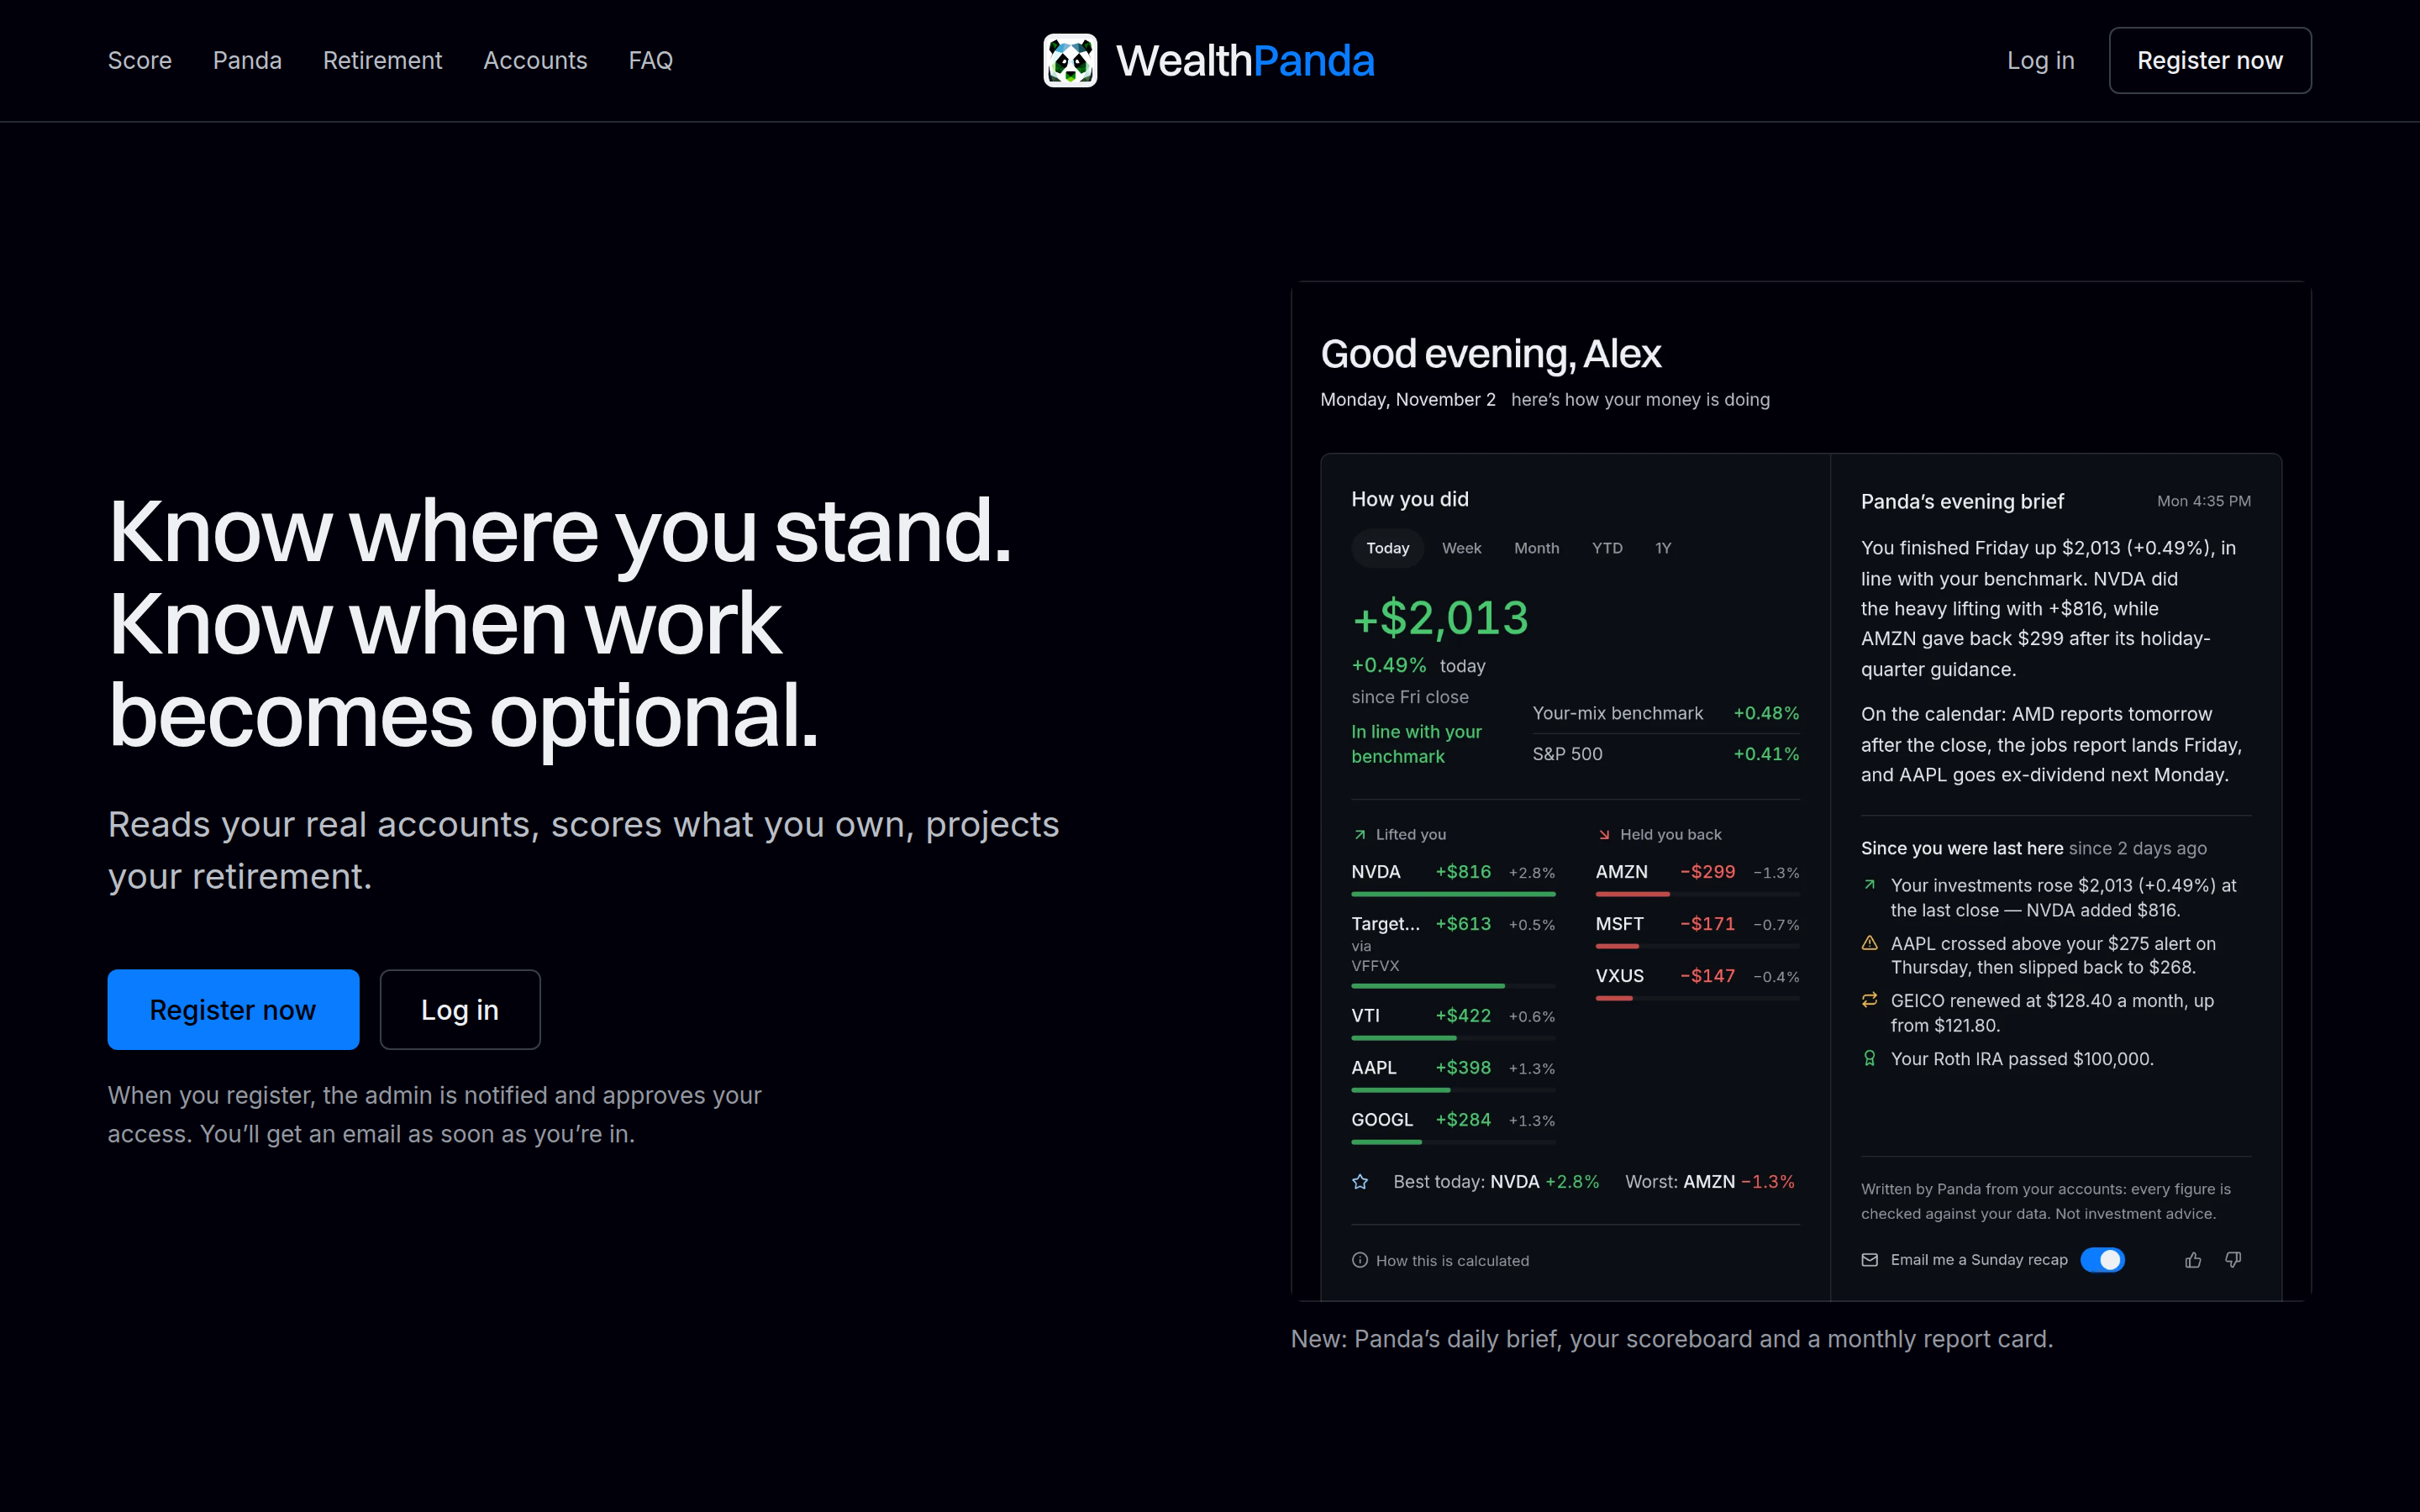
- 2026Panda PodBarcode check-in and check-out for Kumon centers.Ran in production, paused
- 2026World Cup 2026 predictorPicked Spain to win the World Cup, a month before kickoff.Finished
- 2026Live heart rate for remote trainingHeart-rate metrics for an online trainer, Orangetheory style.Working, in progress
- 2026Portfolio agentsA Slack bot for alerts and tracking moves in my stocks and portfolio.Retired into WealthPanda
Gigs, CS2 and a new brewery
# ~/off-hours.yaml
music:
  - electronic gigs
  - rock concerts
game: counter-strike 2
beer: a new brewery, every chance I get
city: chicago